Brian Jemilo II / Services
RAG and LLM engineering
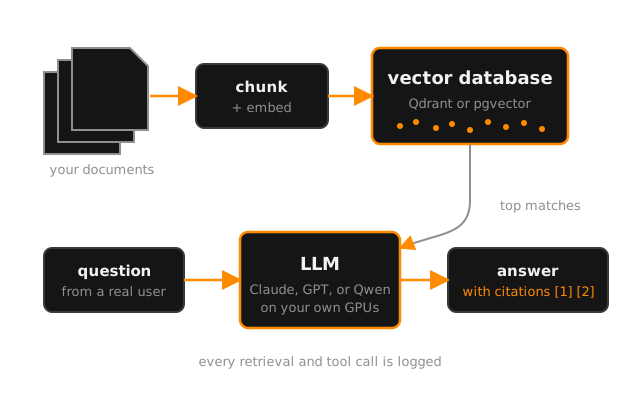
I build RAG systems and LLM apps: chatbots that answer from your own files, agents that can reach your data, and the retrieval layer underneath. Python or TypeScript, LangChain and LangGraph, MCP servers, Qdrant or pgvector. Claude, GPT, or an open model running on your own GPUs.
Work I've done
- At Invent X I designed RAG for law practices: how the documents get chunked, embedded, and retrieved, plus the automation that reads and files them.
- Same client, I built MCP tools so agents could read live API data, with the security, governance, and logging required for production.
- I ran the LLM fine-tuning there for internal knowledge bases and a customer facing chatbot.
- At Shibiko AI, my own company, I built the inference APIs and WebSocket layer for image generation across GPUs on Salad Cloud, Runpod, and AWS, and trained custom diffusion models for enterprise clients.
- OCR and classification for insurance cards at Health iPass. Document extraction at Vokal.
- On GitHub: an MCP server for Umamusume and a few custom ComfyUI nodes.
How I work
Before I touch chunking or swap models I build a small eval set out of real questions people asked. Otherwise there is no way to tell whether a change helped. Retrieval hands back citations to the source, and every tool call an agent makes gets logged.
Tools
Python, TypeScript, LangChain, LangGraph, MCP, Qdrant, pgvector, Anthropic API, OpenAI API, Ollama, Qwen, HuggingFace, PyTorch, Nomic embeddings, FastAPI, n8n
Things people ask me
- Can you add an AI assistant to an app we already have?
- Usually without a rewrite. I put a retrieval layer over your documents or database, expose it through your existing API, and wire it into the frontend you already have.
- TypeScript or Python for RAG?
- Whichever your team runs. Python with FastAPI and LangChain, or TypeScript on Node. The retrieval design is the same in both.
- Can we run models on our own infrastructure instead of OpenAI?
- Ollama or a vLLM style server on your cloud or your GPUs. I've run production inference on Salad Cloud, Runpod, and AWS.
- What is an MCP server and do we need one?
- It's a standard way to expose your tools and data to assistants like Claude. If you want an assistant reading live data from your systems without giving it direct access to your systems, that's usually the cleanest route.
Other things I do
Node.js and TypeScript backends
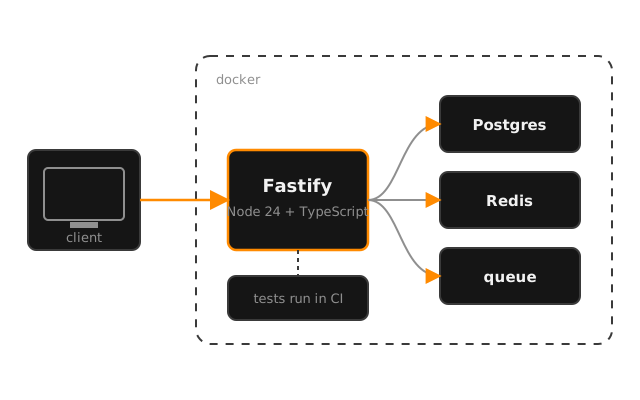
Fastify, NestJS, or Express on Postgres and Redis. I write the tests too.
API development and integrations
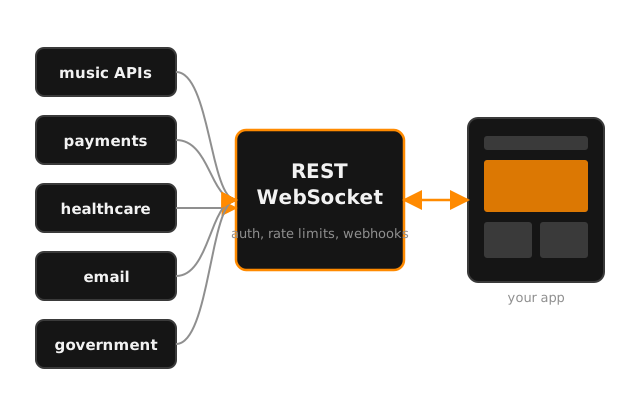
REST and WebSocket APIs, plus third-party integrations.
Web application development
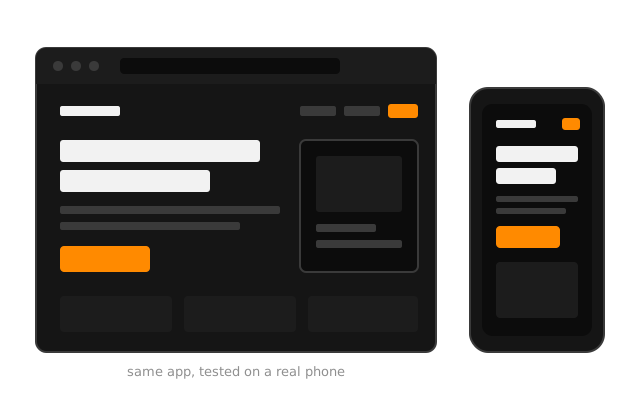
React, Vue, Angular. New builds, or modernizing an older codebase.
Contact
Tell me what you're building or what's broken. I answer within a business day, usually faster.